OpenTelemetry won. In 2026 it is the default way to instrument an application, and the interesting decisions have moved one layer up: which Collector distribution you run, and which backend you point it at.
The OpenTelemetry tools and distributions below cover both. Some are backends built to store and query OTel data natively, some are Collector distributions that bundle the components and support a specific vendor stands behind, and one is the upstream project itself. The ranking favours tools that keep your data in OTel’s own model rather than translating it into something proprietary on the way in.
OpenTelemetry Tools And Distributions At A Glance
#
Tool
Type
Best For
Open Source
Starting Price
1
Kopai
OTel-native backend
Feeding production traces to AI coding agents
Yes (public codebase)
Free alpha, usage-based later, never per seat
2
OpenTelemetry Collector
Upstream Collector (core, contrib, OCB)
Vendor-neutral pipelines you build yourself
Yes (Apache 2.0)
Free
3
Grafana Alloy
Collector distribution
Prometheus and Loki shops
Yes (Apache 2.0)
Free; Grafana Cloud free tier
4
SigNoz
OTel-native backend
Open source, all-in-one traces, logs and metrics
Yes
Self-hosted free; cloud from $0.30/GB traces
5
Jaeger
Tracing backend
Zero-licence-cost distributed tracing
Yes (CNCF graduated)
Free
6
AWS Distro for OpenTelemetry
Collector distribution
AWS-native pipelines with AWS support
Yes
Free (AWS backend costs apply)
7
Elastic Distribution of OpenTelemetry
Collector and SDK distribution
Elasticsearch-backed observability
Yes
Free; Elastic Cloud from $99/mo
8
Splunk Distribution of OpenTelemetry Collector
Collector distribution
Splunk Observability Cloud customers
Yes
Free; Splunk from $15/host/mo
9
Datadog Distribution of OpenTelemetry Collector
Collector distribution
Datadog customers moving to OTel
Yes
Free; Datadog from $15/host/mo
10
OpenObserve
OTel-native backend
Lightweight single-binary storage on object storage
Yes (AGPL-3.0)
Free up to 50 GB/day self-hosted
What Is OpenTelemetry?
OpenTelemetry, usually shortened to OTel, is an open standard for generating and moving telemetry data out of software. It is a CNCF project and the second most active in that foundation after Kubernetes. What it standardises is the part that used to be proprietary: how an application describes what it is doing, and how that description travels to whatever tool stores it.
Four pieces make up the project. The specification and its semantic conventions define the data model, so a database call or an HTTP request is described the same way whatever language emitted it. The SDKs and APIs, available for every major language, do the instrumenting, either explicitly in code or through auto-instrumentation agents that require no code changes. OTLP is the wire protocol everything speaks. And the Collector is the pipeline component that receives telemetry, processes it and exports it onward.
It covers three signals. Traces follow a single request across services. Metrics are the numeric time series, counters, gauges and histograms. Logs are the events, brought into the same model so they carry the same trace and resource context as everything else. OpenTelemetry generates and ships all three. It deliberately does not store or visualise them, which is why every list of OpenTelemetry tools is really a list of two things: pipelines that move the data, and backends that keep it.
The practical payoff is that instrumentation stops being a vendor decision. Instrument once against the standard, and changing backends becomes a configuration change in the Collector rather than a re-instrumentation project across every service you own.
Best OpenTelemetry Tools And Distributions In 2026
1. Kopai — OpenTelemetry Under The Hood, Built For AI Coding Agents
Kopai is an OpenTelemetry-native backend with a different customer in mind: the AI coding agent that is fixing your bug. It stores production traces and serves them, with the evidence attached, to Claude, Cursor, Copilot, Windsurf, Codex, Lovable and Replit, so the agent can find the root cause and propose a fix a human then approves.
The OTel foundation is what makes the setup so short. One command, npx @kopai/cli connect, auto-detects the application and instruments its API routes, and because it rides on OpenTelemetry the same command covers Node, Python, Go and more than eight other languages. There is no proprietary agent and no translation layer between the OTel data and what the coding agent sees. Dashboards are generated on demand from a plain-English request rather than built by hand, and any error, status code or trace can be pulled by asking for it.
The codebase is public on GitHub, the alpha is free with no credit card, and traces stay encrypted, isolated and exportable at any time. Kopai has committed to a single usage-based price after launch, never per seat, which suits teams where every developer runs an agent. Alerting is on the roadmap for Q3 2026 and autonomous issue investigation for Q4 2026. It is not an incident-response or on-call product, so keep your paging tool; Kopai is the trace store the agent reads from.
Best for: teams that already emit OpenTelemetry and want their coding agents debugging production from it.
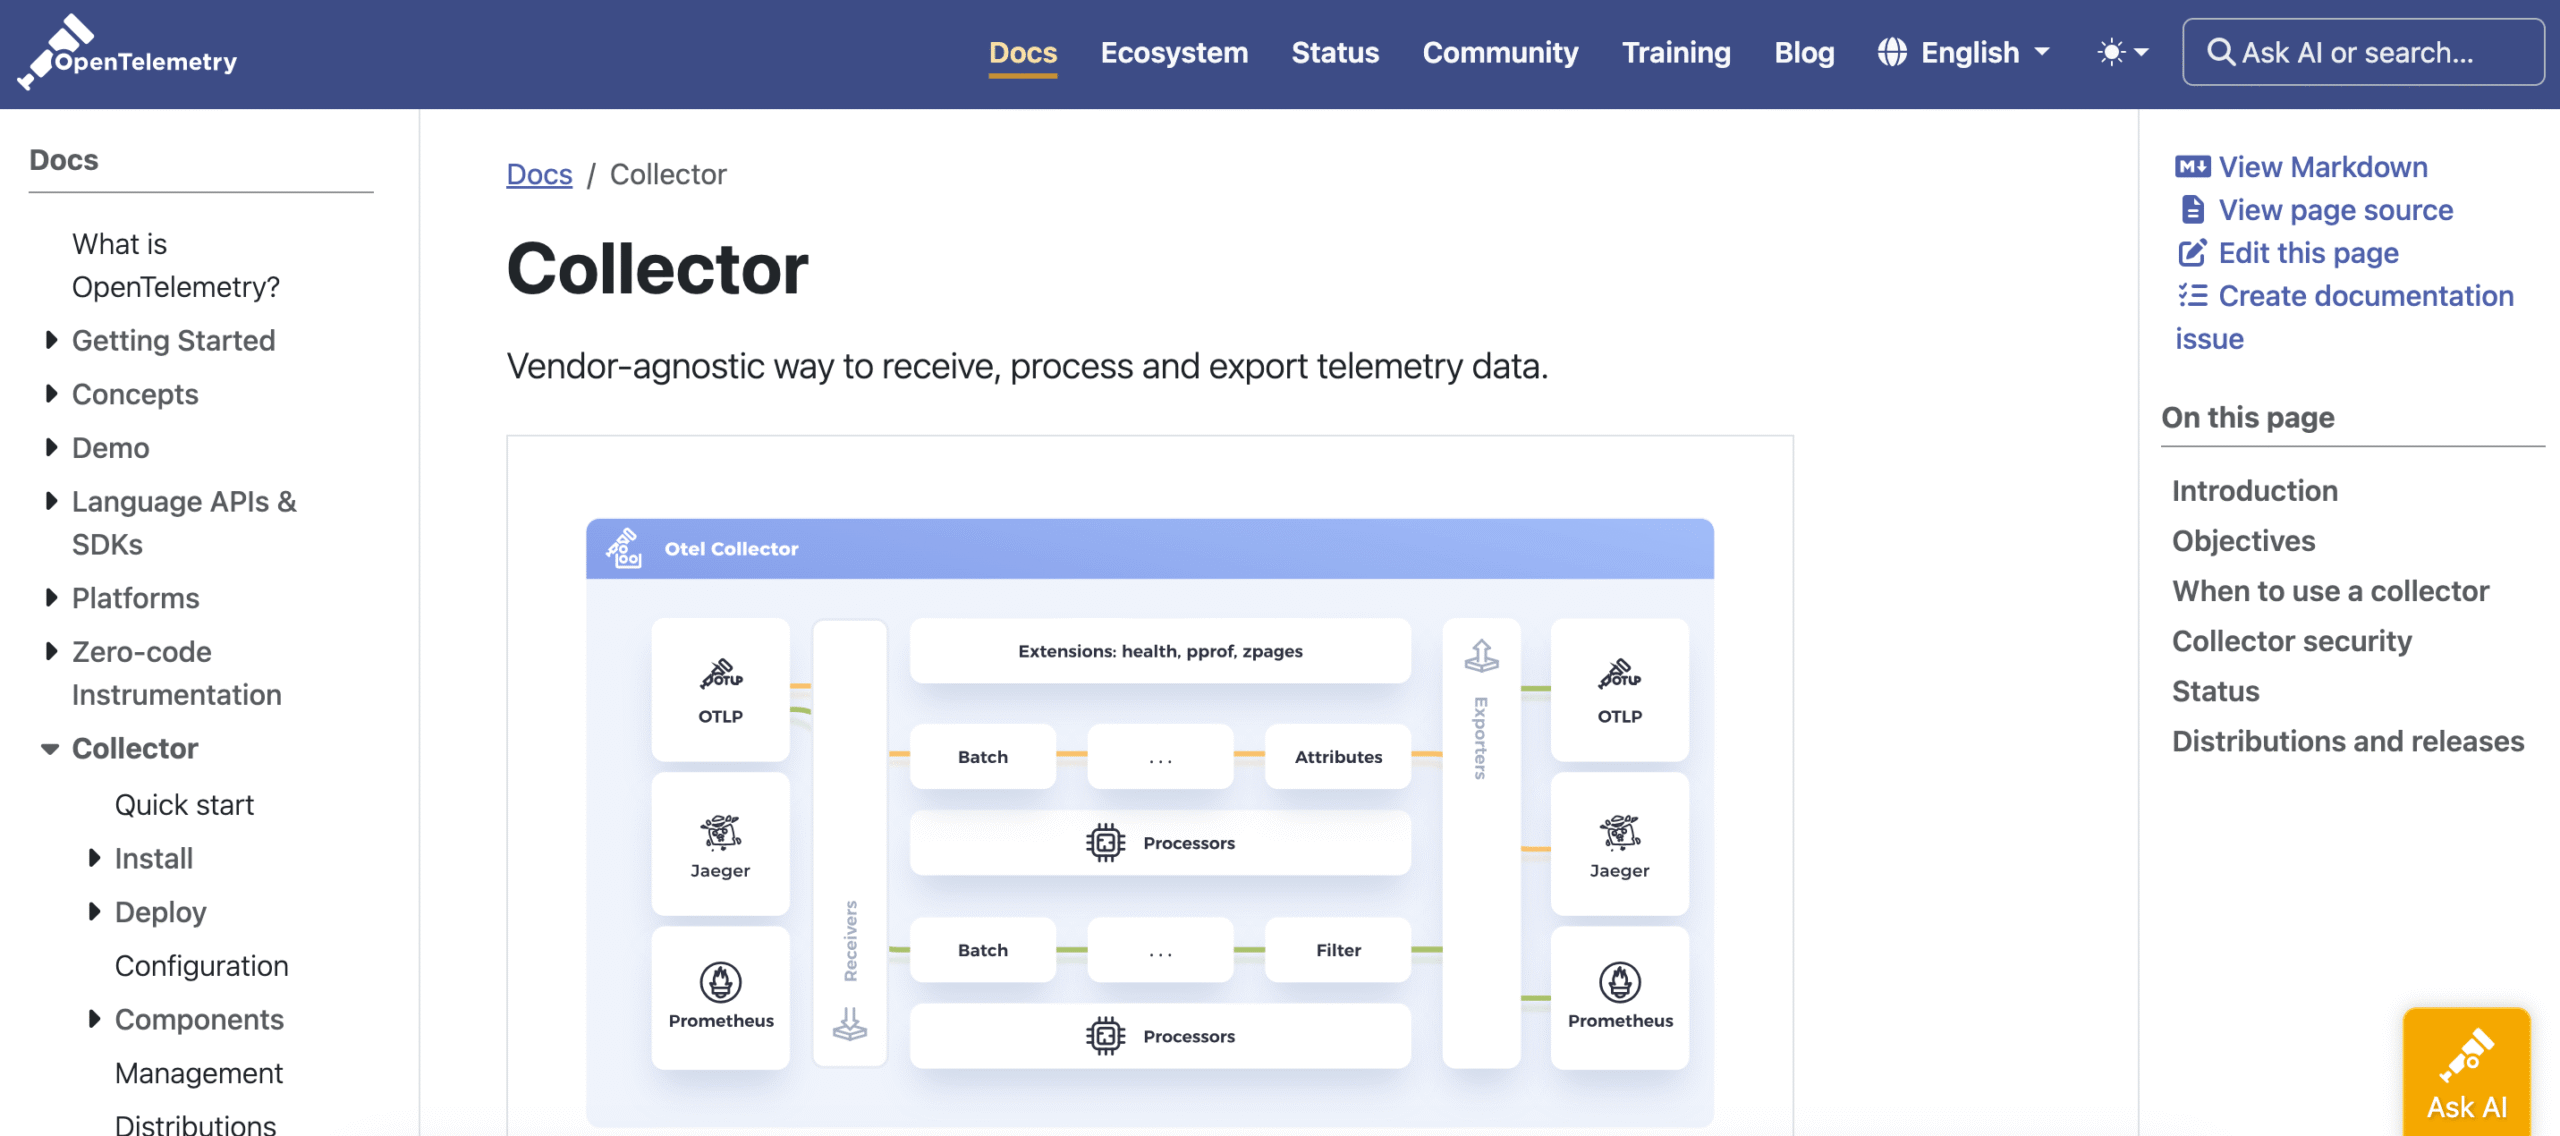
Every distribution on this list starts here. The upstream OpenTelemetry Collector, the OTel Collector in most documentation, ships in two flavours. Core is the curated foundation: OTLP receivers and exporters, the basic processors, a handful of extensions, and the common receivers and exporters for Prometheus, Kafka, Jaeger, Zipkin and file. Contrib (the opentelemetry-collector-contrib repository) is the Swiss army knife, with hundreds of community-contributed components, and it is where most vendor-specific exporters live.
The third piece is the OpenTelemetry Collector Builder (OCB), which lets you compile a Collector containing only the components you use. That is how most serious teams run it in 2026: a lean custom binary rather than the full contrib image. Running upstream means you get every release the day it lands and owe nobody a support contract, at the cost of doing your own upgrades and troubleshooting. It is Apache 2.0 licensed, CNCF governed and free.
Best for: platform teams that want vendor-neutral pipelines and are happy to own them.
3. Grafana Alloy — The Collector Distribution For Prometheus And Loki Shops
Alloy is Grafana’s OpenTelemetry Collector distribution, and it is the one that looks least like the others. Instead of YAML it uses an HCL-like configuration language, and it ships with native Prometheus and Loki integration plus a built-in UI for inspecting the pipeline. If your team already speaks PromQL and LogQL, Alloy is the shortest path from OpenTelemetry to Grafana.
Behind it sits the Grafana stack: Tempo for traces, Loki for logs and Mimir for metrics, each open source and each with its own query language, which is the trade-off to weigh. Grafana Cloud’s free tier includes 50 GB of traces, and Tempo’s adaptive sampling helps keep trace storage costs down as volume grows. Alloy itself is Apache 2.0 and free.
Best for: teams standardised on Grafana dashboards who want an OTel pipeline that fits the stack they have.
4. SigNoz — Open Source Traces, Logs And Metrics On ClickHouse
SigNoz is built entirely on OpenTelemetry standards and stores everything in ClickHouse, which is why it can hold traces, logs and metrics in a single interface with APM views and dashboards on top. It preserves OTel resource attributes as distinct, queryable context rather than flattening them, and it documents LLM observability support alongside the conventional signals.
The self-hosted community edition is free, with commercial enterprise features layered on. SigNoz Cloud is ingestion-priced, with traces at $0.30 per GB. For teams that want the Datadog experience without the Datadog bill, and without handing their telemetry to a proprietary data model, this is the open source OpenTelemetry backend with the most momentum in 2026.
Best for: teams that want one open source backend for all three signals.
5. Jaeger — CNCF-Graduated Tracing At Zero Licence Cost
Jaeger is the CNCF-graduated distributed tracing backend, and its current major version is built directly on the OpenTelemetry Collector, so it consumes OTLP natively and can be extended with Collector components. Its focus is traces: service dependency graphs, trace search and comparison, and optional Service Performance Monitoring derived from span metrics.
It does not try to be a logs or metrics platform, which keeps it small and predictable to run. For teams that need OpenTelemetry tracing, own their infrastructure and want no licence cost at all, Jaeger remains the reference choice among distributed tracing tools.
Best for: teams that need a dedicated, free tracing backend with minimal infrastructure.
ADOT is Amazon’s supported build of the OpenTelemetry Collector and SDKs. It bundles the AWS-specific pieces, including the EMF exporter for CloudWatch and the X-Ray components, tested and packaged for EC2, ECS, EKS and Lambda. AWS Premium Support covers it, which is the main reason to choose it over upstream if you run on AWS.
The trade-off is lag. ADOT typically trails upstream releases by one to three months, so brand-new Collector features arrive later. The distribution itself is open source and free; you pay for whatever AWS backend it feeds.
Best for: AWS-heavy teams that want a supported Collector rather than a self-maintained one.
EDOT is Elastic’s distribution of both the Collector and the language SDKs, tuned for shipping into Elasticsearch. What sets it apart in 2026 is that Elastic now stores OTel data in native data streams that retain the semantic conventions, rather than remapping everything into the older APM schema, so what you query in Kibana is what your instrumentation emitted.
Configuration is standard YAML and the distribution typically lags upstream by one to two months. The Collector and SDKs are free; Elastic Cloud starts at $99 a month, with serverless consumption-based and self-managed options as well. Support for OTel data across the wider Elastic product is still uneven, so check the specific features you need.
Best for: teams already running Elasticsearch who want first-class OTel ingestion.
Splunk was one of the earliest large vendors to standardise on OpenTelemetry, and its Collector distribution, usually called the Splunk OTel Collector, shows it: an installer script, standard YAML configuration, and a set of Splunk-specific receivers and exporters. Splunk support plans cover it and it typically runs one to two months behind upstream.
On the backend side, Splunk Observability Cloud is host-based from $15 to $75 per host per month or activity-based, and requires an annual contract. The backend is split, with metrics on SignalFlow, traces in Splunk APM and logs handled separately, so it is less unified than the OTel-native options higher on this list.
Best for: existing Splunk customers who want a vendor-supported Collector.
DDOT is Datadog’s own Collector distribution, and it embeds the Collector inside the Datadog Agent so teams can run OTel pipelines without giving up Agent features. Configuration stays YAML-compatible with upstream and the distribution typically lags by one to two months.
The catch is what happens to the data on arrival. Datadog supports several OpenTelemetry ingestion paths over OTLP but translates everything into its own data model, so some OTel semantics do not survive the trip. Pricing is metered across hosts, containers, custom metrics, spans, logs and users, with infrastructure from $15 per host per month. For a team already on Datadog with more than 700 integrations in play, DDOT is the pragmatic on-ramp to OpenTelemetry.
Best for: Datadog customers who want OTel instrumentation without leaving the Agent.
10. OpenObserve — A Single Rust Binary Backed By Object Storage
OpenObserve is the lightweight option. It is a single Rust binary that ingests OTLP traces, logs and metrics and persists them as Parquet files in object storage, which makes long-term retention cheap and the deployment footprint tiny. It can run as a single node, a distributed cluster or a managed cloud service.
The community edition is AGPL-3.0 licensed and free up to 50 GB of daily ingestion, with a commercial edition and consumption-priced cloud above that. It is a good fit for teams that find ClickHouse-based platforms heavier than they need.
Best for: small teams and edge deployments that want OTel storage without a database cluster.
OpenTelemetry Versus Prometheus, Jaeger And Vendor Agents
The comparison people reach for most is OpenTelemetry versus Prometheus, and it is the one that misleads most, because they are not the same kind of thing. Prometheus is a metrics system: a data model, a scrape-based collection method, a time series database and PromQL. OpenTelemetry is an instrumentation standard covering traces, metrics and logs, with no storage and no query language of its own. The two work together far more often than they compete. OTel can emit in Prometheus format, the Collector can scrape Prometheus endpoints, and a common 2026 setup is OTel instrumentation feeding Prometheus or Mimir for metrics while traces go somewhere else.
Jaeger is the same story one signal over. It is a tracing backend, not an instrumentation standard, and its current version is built on the OpenTelemetry Collector. You instrument with OTel and store in Jaeger. They are layers, not alternatives.
The real alternative to OpenTelemetry is a proprietary vendor agent: the Datadog Agent, New Relic’s agents, the older Elastic APM agents. Those are genuinely competing choices, and the trade is convenience now against portability later. A vendor agent is usually a faster first install and comes with deeper product integration. It also means your instrumentation belongs to that vendor, and changing backends means re-instrumenting every service rather than editing a Collector config. That is the single reason OpenTelemetry became the default: the instrumentation outlives the decision about where to send it.
How To Choose An OpenTelemetry Tool Or Distribution
Do You Need A Collector, A Backend, Or Both?
The Collector moves and shapes telemetry; the backend stores and queries it. Upstream, Alloy, ADOT, EDOT, Splunk and DDOT are Collector distributions. Kopai, SigNoz, Jaeger and OpenObserve are backends. Most teams end up with one of each, so pick the backend first and let it steer the Collector choice.
Does The Backend Keep OTel’s Data Model?
Some backends store OpenTelemetry data as-is, with resource attributes and semantic conventions intact. Others translate it into a proprietary entity model on ingest, which can lose detail and lock in your queries. Kopai, SigNoz, OpenObserve and Elastic’s native data streams keep the model; the enterprise APMs generally do not.
Who Is Reading The Data?
Dashboards for humans and evidence for AI coding agents are different products. If your developers lean on Claude Code or Cursor to debug, an agent-first backend like Kopai will earn its place faster than another dashboard. For the wider field of agent-facing tools, see our list of the top observability tools for AI coding agents.
How Far Behind Upstream Can You Afford To Be?
Vendor distributions lag upstream by one to three months. That is fine for most teams and a real problem for a few. If you need every new receiver the week it ships, run upstream or build with OCB.
What Does Support Look Like?
Upstream gives you a community. ADOT, EDOT, Splunk and DDOT give you a support contract. Decide how much that contract is worth against the cost of maintaining the pipeline yourself.
What Will Ingestion Actually Cost At Your Volume?
Telemetry bills grow faster than traffic does, and the pricing units on this list are not comparable to each other: per GB ingested for SigNoz, per host for Splunk and Datadog, metered across half a dozen dimensions once you add spans, custom metrics and logs. Before committing, estimate your daily GB and your span count, then price two or three candidates against those numbers rather than against their headline rates. Sampling is the other half of the answer. Tail-based sampling in the Collector, or adaptive sampling in Tempo, decides the bill more than the vendor does.
Frequently Asked Questions
What is OpenTelemetry used for?
OpenTelemetry is used to instrument applications once, in a vendor-neutral way, and send the resulting traces, metrics and logs to any backend. Teams use it to follow a request across microservices, measure latency and error rates, correlate logs with the request that produced them, and keep the freedom to change observability vendors without touching application code.
What is the OpenTelemetry Collector?
The Collector, often called the OTel Collector, is a vendor-neutral service that receives telemetry, processes it and exports it to one or more backends. It is built from receivers, processors, exporters and extensions assembled in a pipeline. Core is the curated build, contrib carries hundreds of community components, and the OpenTelemetry Collector Builder compiles a binary containing only the components you actually use.
Do I need a Collector, or can I send data straight to a backend?
You can export directly from the SDK, and for a small system that is fine. A Collector earns its place as soon as you want batching and retries, sampling, attribute scrubbing before data leaves your network, or the ability to fan out to more than one backend. It also means changing backend is a config change rather than a redeploy of every service.
What is an OpenTelemetry distribution?
A distribution, or distro, is a pre-built package of the upstream Collector and sometimes the SDKs, bundled with a vendor’s own components, tested and supported by that vendor. ADOT, EDOT, the Splunk and Datadog distributions and Grafana Alloy are all distributions. You get support and a shorter setup; you accept a release lag of one to three months behind upstream.
What is the best OpenTelemetry backend?
It depends on who reads the data and how much of it you keep. Kopai is the pick when AI coding agents are the ones debugging production. SigNoz is the strongest open source all-in-one backend for traces, logs and metrics, Jaeger is the leanest choice if you only need tracing, and OpenObserve suits teams that want cheap long-term retention on object storage.
Is OpenTelemetry free?
Yes. OpenTelemetry is an Apache 2.0 licensed CNCF project, and the Collector, SDKs and every distribution on this list are free to use. The cost sits in the backend that stores and queries the data, and in the infrastructure you run it on. Self-hosting Jaeger, SigNoz or OpenObserve keeps licence cost at zero and moves the expense to storage and operations.
Is OpenTelemetry a replacement for Datadog?
No. OpenTelemetry replaces the Datadog Agent’s instrumentation, not the Datadog platform. Datadog is a backend and OpenTelemetry is the standard that feeds it, so the usual comparison is really OTel instrumentation against proprietary instrumentation. Datadog accepts OTLP data and ships its own Collector distribution, so teams can adopt OpenTelemetry and stay on Datadog, or keep the instrumentation and move to an OTel-native backend later.
What are the alternatives to OpenTelemetry?
Proprietary vendor agents from Datadog, New Relic, Dynatrace and others, and older open standards such as OpenTracing and OpenCensus, both of which merged into OpenTelemetry and are no longer maintained. Prometheus and Jaeger are frequently listed as alternatives but are not: Prometheus is a metrics backend and Jaeger a tracing backend, and both work with OTel instrumentation rather than replacing it.
Can OpenTelemetry handle logs as well as traces and metrics?
Yes, and logs are the most recent of the three signals to stabilise. The value of routing them through OTel is correlation: a log record carries the same trace and resource context as the span it happened inside, so you can move from a failing request to the exact log lines it produced. SigNoz, OpenObserve, Elastic and the Grafana stack all handle all three signals.
Conclusion
The OpenTelemetry tools and distributions that matter in 2026 are the ones that let you keep the data model you worked hard to instrument. Kopai takes the top slot for turning an OTel trace store into something a coding agent can debug from, with one command to connect and no per-seat pricing. The upstream Collector and Grafana Alloy are the pipelines most teams will run, SigNoz, Jaeger and OpenObserve are the open source backends worth self-hosting, and the AWS, Elastic, Splunk and Datadog distributions are the supported routes into the platform you already pay for. Whichever you choose, keep the instrumentation vendor-neutral so the next decision is as easy as this one. For adjacent shortlists, see our list of the top enterprise data collection platforms.
If you want to feature your OpenTelemetry tool or distribution on this list, email us or submit a form in the Top Choices section. After a thorough assessment, we’ll decide whether it’s a valuable addition.